September 26, 2026
Starting as a QA engineer at a new company in 2026 means walking into a system that has been accumulating technical debt, undocumented assumptions, and coverage gaps for years — sometimes decades. The onboarding challenge is not learning a new codebase in isolation: it is simultaneously auditing what quality infrastructure exists, identifying the highest-risk gaps, and building credibility with a team that has been shipping without you. The engineers who do this well in the first 30 days set the pace for everything that follows; those who skip straight to writing tests inherit problems they cannot see.
This guide covers a structured approach to QA onboarding: what to audit in the first week, how to map risk against the existing test suite, what baseline metrics to establish, and where to prioritize new coverage. For foundational context on testing strategy, see Astaqc’s complete software testing guide and resources on manual testing and test automation services. Teams looking to accelerate QA onboarding or establish a testing function from scratch can engage Astaqc’s QA team services.
The most expensive QA mistake at a new company is writing tests before auditing what already exists. If you start contributing to a suite you do not fully understand, you will duplicate coverage in low-risk areas, miss the gaps that matter, and anchor your mental model of the system to whatever the existing tests happen to cover rather than to the actual system behavior.
A first-week audit has four components. The first is a structural inventory: how many tests exist, how they are organized (by feature, by layer, by service), which testing frameworks are in use, and where the tests live in the repository. This takes one to two hours and gives you the map. The second is a coverage review: which user flows, API endpoints, and system components have test coverage and which do not. Most organizations have no formal coverage map; you will need to build one by reading the tests and cross-referencing them against product documentation and API specs. The third is a flakiness audit: which tests fail intermittently on CI without a corresponding application bug. Flaky tests are the single biggest signal of test suite health problems and the fastest way to identify where the team has lost trust in their own tests. The fourth is a tooling review: what test infrastructure exists (CI configuration, test data management, environment setup), where it breaks, and what manual workarounds the team has built around its limitations.
The output of the first week should be a written audit document, not a verbal debrief. Writing it forces precision about what you found, creates a baseline you can reference in 90 days, and demonstrates to the engineering team that QA onboarding at this company produces something tangible. Astaqc’s manual vs automated testing guide covers how to assess the right balance between the two as part of this initial audit.
Not all untested code carries equal risk. A missing test for a rarely-used admin setting is different from a missing test for the checkout flow that processes all revenue. Risk mapping is the process of ranking gaps by the combination of failure probability and failure consequence — and it is the single most important analytical output of the first 30 days for a new QA engineer.
Failure probability comes from change frequency and complexity. Features that change in every sprint are higher probability failures than features that have not been touched in two years. Complex business logic with multiple conditional branches is higher probability than a simple read-only display component. Your version control history provides the data: a git log --follow -p run against the most frequently modified files gives you the change frequency signal in under an hour. Code complexity can be approximated by cyclomatic complexity tools (most static analysis suites include one) or estimated manually by reading the files and counting conditional branches.
Failure consequence comes from business impact. Revenue paths (checkout, subscription management, payment processing) are maximum consequence. Authentication and authorization failures have both revenue and security consequence. Data export and import paths have consequence from data integrity risk. Features used by the highest-volume users have consequence from exposure. The product roadmap and customer support tickets are your primary data sources for consequence: where is the company investing, and where do bugs cause the most inbound pain?
Risk = probability × consequence. Build a simple two-axis matrix with your highest-probability features on one axis and your highest-consequence features on the other. The upper-right quadrant — high probability, high consequence — is where you write tests first, regardless of what already exists. If that quadrant has coverage, validate it: high-probability, high-consequence coverage is worth reviewing in detail to confirm it is testing what it claims to test, not just green on CI. See Astaqc’s guide on shift-left testing for how to integrate risk-based prioritization into sprint planning rather than treating it as a one-time onboarding exercise.
The baseline you establish in the first 30 days becomes the reference point for every quality conversation you have at this company for the next several years. Establishing it carefully — and documenting how it was measured — is worth more than most of the test-writing work you will do in the same period.
Three metrics are worth establishing on day one: defect escape rate, test suite execution time, and flaky test percentage. Defect escape rate is the percentage of defects found in production versus those found before production. It is the most direct measure of whether the test suite is doing its job. Your CI/CD platform and bug tracker together provide the numerator (production defects filed) and denominator (total defects filed); the ratio tells you how much of the risk the current suite is absorbing. Test suite execution time matters because suites that take more than 20 minutes to run on CI create feedback-loop problems that push developers to skip running tests locally, which means defects arrive in the suite rather than being caught before commit. Flaky test percentage is the percentage of test runs that produce a different result on re-run without any application code change; a suite above 5% flakiness has lost developer trust and is generating false confidence.
Two additional metrics are worth establishing in the first month: coverage by risk tier (the percentage of high-risk features from your risk map that have coverage), and mean time to fix a failing test (how long the team takes to address a broken test in CI). The second metric is a cultural signal more than a technical one: if broken tests sit for days without attention, the team treats the test suite as advisory rather than blocking, which means your coverage improvements will face organizational resistance before they face technical challenges.
Avoid vanity metrics during onboarding. Line coverage percentage is the most common one: a suite with 90% line coverage can still miss all the critical conditional paths that represent real risk. Statement coverage tells you what code was executed during a test run, not whether the assertions validate the correct behavior. Tracking these is not wrong, but leading with them in conversations with engineering leadership signals that you are optimizing for the wrong thing. See Astaqc’s regression testing guide for how to connect coverage metrics to defect escape prevention in a way that resonates with non-QA stakeholders.
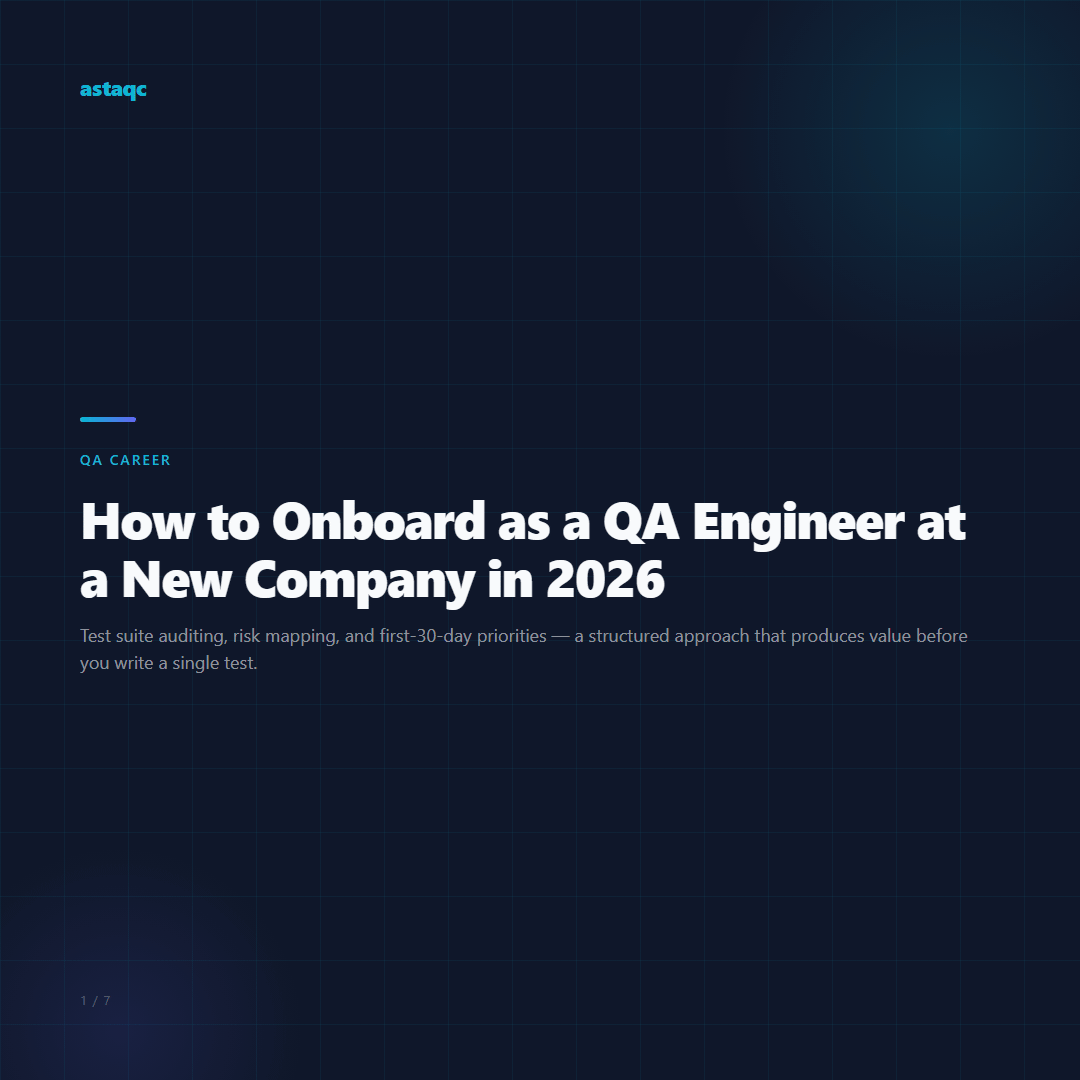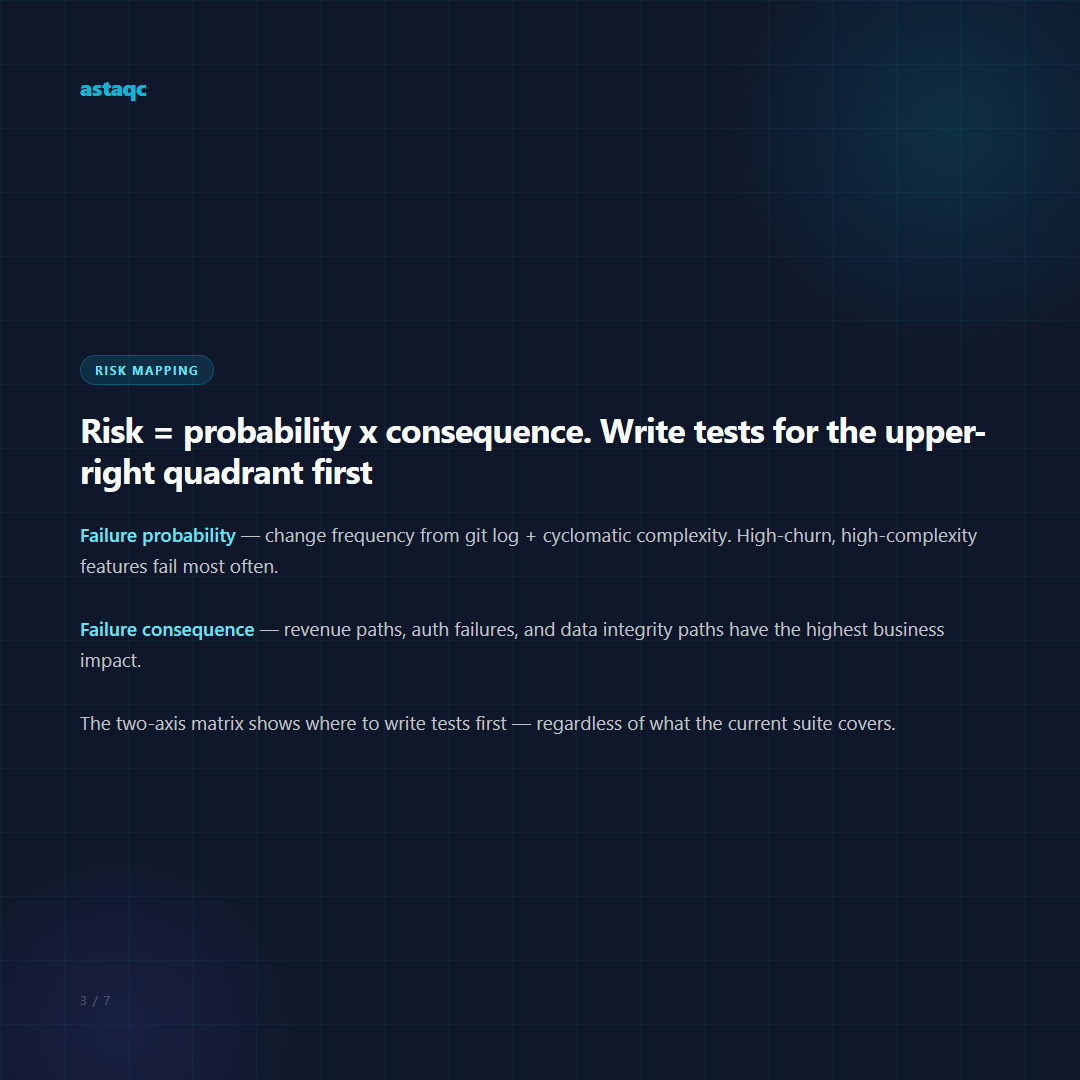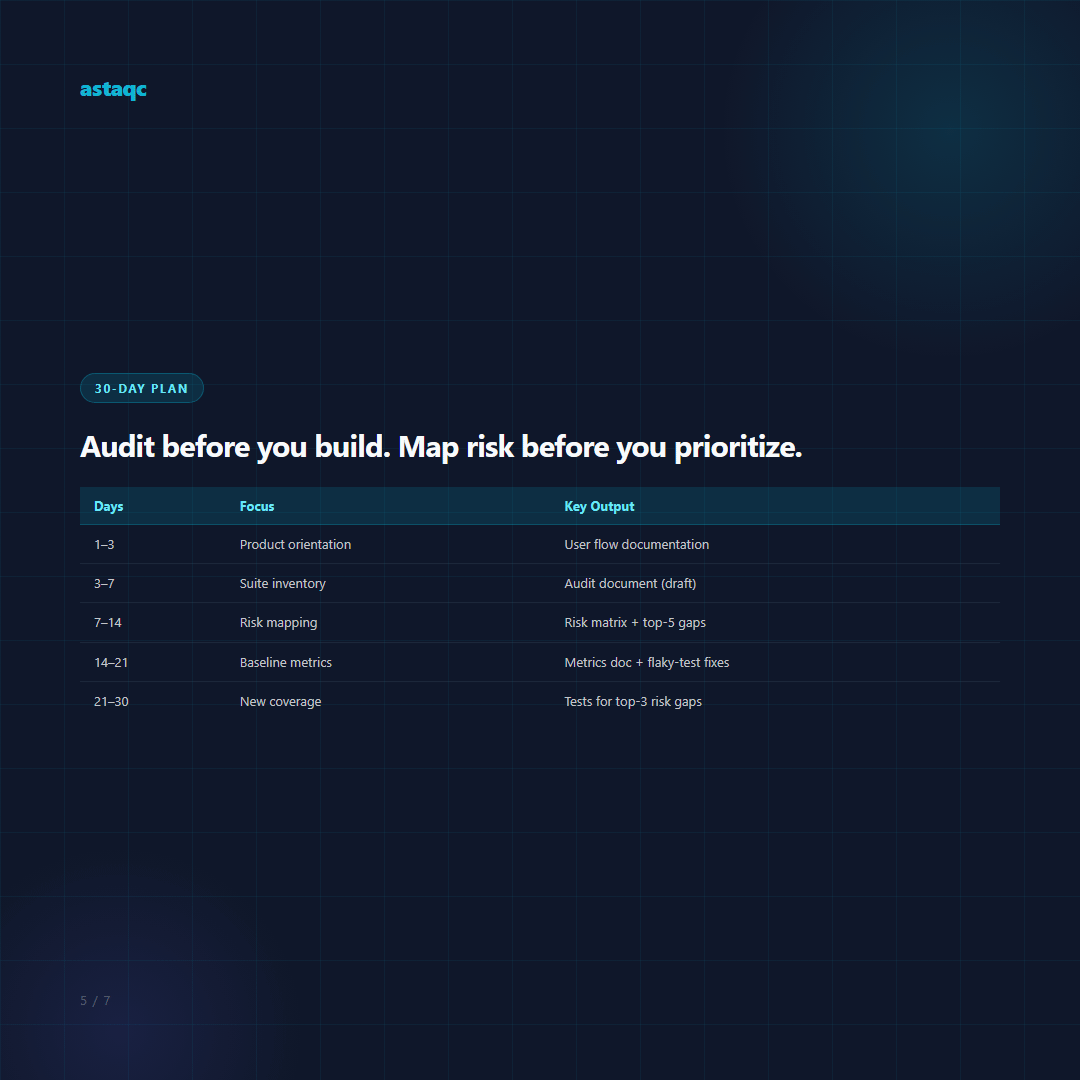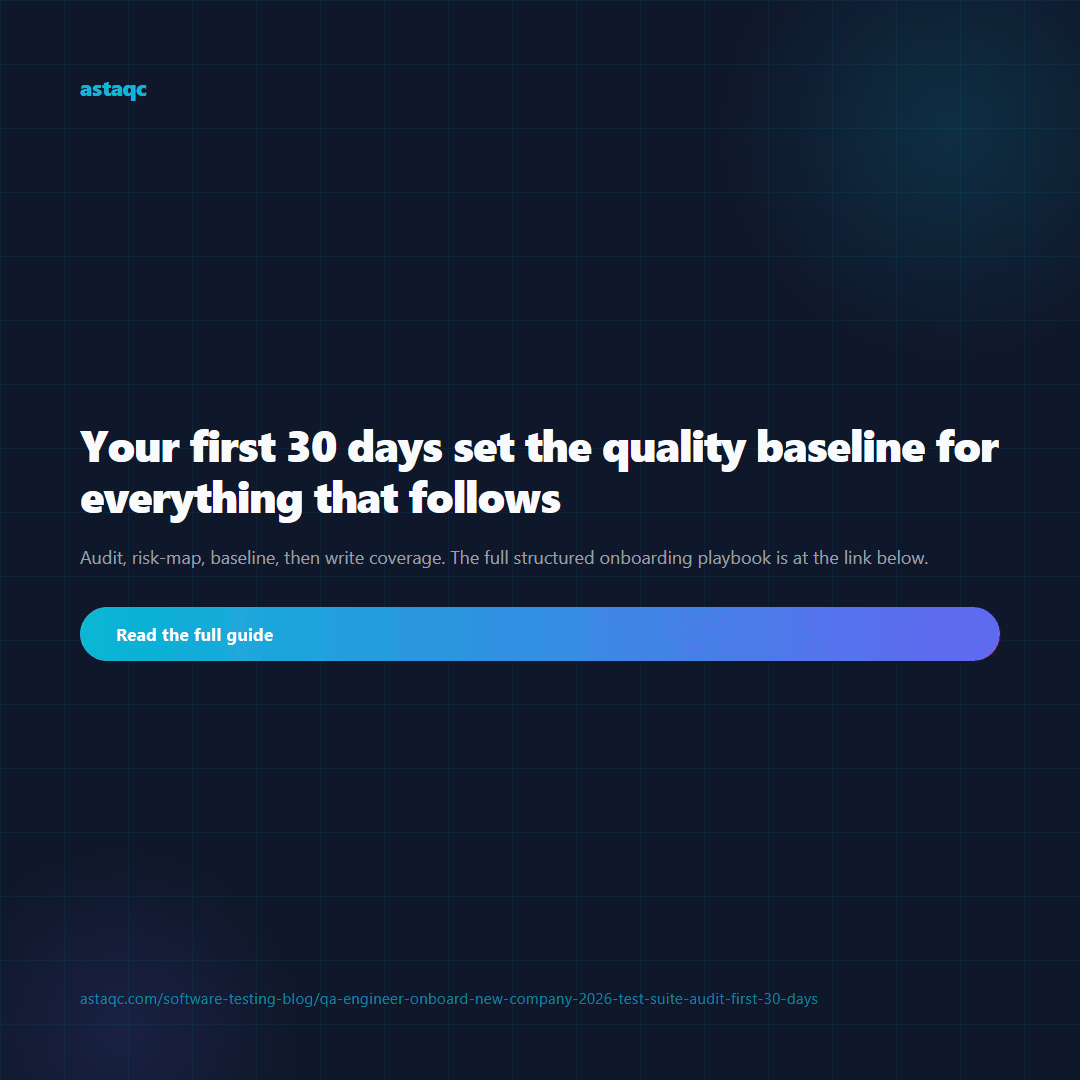
The following sequence applies to most QA onboarding situations at product companies. Adjust for context — a startup with no test suite needs a different sequence than an enterprise with a 50,000-test monorepo — but the underlying logic holds: audit before you build, map risk before you prioritize, establish baselines before you make claims.
Days 1–3: Shadow the product. Use the application as a user, not as a tester. Walk every major user flow without looking for bugs. Read customer-facing documentation, onboarding materials, and the last three months of release notes. The goal is to internalize what the product is supposed to do before evaluating how well it is tested.
Days 3–7: Run the structural inventory. Count and categorize tests, identify frameworks and tooling, map the CI configuration. Write the audit document in draft form. Schedule a 30-minute conversation with the most tenured QA engineer or developer who owns testing if one exists, and use it to validate your structural read and identify what the written documentation does not capture.
Days 7–14: Build the risk map. Cross-reference change frequency data from version control with consequence data from the product roadmap and support tickets. Fill in the two-axis matrix. Identify the top five to ten highest-risk gaps in the current suite. This output is worth presenting to the engineering lead; it demonstrates analytical value before you have written a single test.
Days 14–21: Establish baselines. Measure defect escape rate, execution time, and flakiness percentage. Document the measurement methodology so it can be repeated consistently. Begin addressing the highest-severity flaky tests — these have the fastest return on time invested because each fix restores trust in existing coverage rather than building new coverage from zero.
Days 21–30: Write the first new coverage. Target the high-risk gaps identified in your risk map. Use whatever tools are already in place — this is not the time to introduce a new framework or tooling change, even if the current tooling is suboptimal. Tooling changes require team buy-in that you have not yet built. Deliver coverage that works within the existing system, then propose improvements from a position of demonstrated output.
| Days | Focus | Key Output | Stakeholder |
|---|---|---|---|
| 1–3 | Product orientation | User flow documentation | Self |
| 3–7 | Suite inventory | Audit document (draft) | QA lead or eng team |
| 7–14 | Risk mapping | Risk matrix + top-5 gaps | Engineering lead |
| 14–21 | Baseline metrics | Metrics doc + flaky-test fixes | Engineering team |
| 21–30 | New coverage | Tests for top-3 risk gaps | Engineering lead + QA team |
A near-zero coverage starting point changes the sequencing slightly but not the logic. Skip the flakiness audit (there are no tests to be flaky) and spend more time on the risk mapping phase, since your first coverage needs to be highly targeted to matter. In this scenario, the risk map and the 30-day priority list are your entire strategy rather than a guide for improving an existing suite. Document the starting state explicitly — zero coverage is a powerful baseline that makes every subsequent improvement legible to non-technical stakeholders. Astaqc’s test automation services are specifically designed for teams building coverage from this starting point and can accelerate the foundation-building phase significantly.
Cultural resistance to testing is a confidence problem, not a knowledge problem. Teams that deprioritize testing have usually had experiences where the test suite created friction without catching bugs that mattered — the flaky-test problem, tests that passed while production burned, slow CI that made development painful. Address the confidence problem first: fix the most visible pain points (flaky tests, slow CI, tests that clearly do not match current behavior) before proposing new coverage. Once the team sees that the test suite is something they can trust and that it speeds them up rather than slowing them down, the cultural resistance tends to dissolve. Coming in with a testing mandate before demonstrating value usually accelerates the resistance.
The right answer during the first 30 days is “whatever the team already uses.” Even if the current tooling is clearly suboptimal — an unmaintained framework, a slow test runner, a CI configuration that makes parallel execution impossible — recommending a tooling change in the first month costs political capital you have not yet earned. Document the tooling gaps in your audit, propose improvements at the 60-day mark when you have demonstrated output, and frame proposals around specific pain points you have observed rather than abstract best practices. For no-code test automation tools like TestInspector that can sit alongside existing frameworks without displacing them, early adoption is lower risk because it adds coverage rather than requiring migration. See TestInspector and Astaqc’s software testing services for options that integrate with existing QA workflows.
Two metrics land with non-technical stakeholders: defect escape rate (what percentage of bugs reach users) and the risk map (which high-value features have no test coverage). Both translate directly to business risk language that resonates outside engineering. Avoid presenting line coverage percentages or test counts to non-technical stakeholders — these numbers have no intuitive meaning outside QA and tend to generate counterproductive conversations about whether the number is “good enough.” The risk map is particularly effective because it reframes testing as a risk management activity rather than a development artifact, which aligns with how leadership already thinks about product decisions. Astaqc’s QA team services include quality reporting frameworks designed specifically for this stakeholder communication challenge.
Push back only after you have demonstrated that you can work within the existing architecture. This is a sequencing rule, not a permanent constraint. A new QA engineer who critiques the test architecture in week one, before writing a single test, is seen as a critic; the same engineer who delivers demonstrable coverage improvements in month one and then proposes architectural changes in month two is seen as a contributor who has earned the conversation. The exception is active harm: if the current architecture contains a practice that is actively causing production incidents or masking real failures, flag it immediately and escalate through the engineering lead rather than treating it as a deferred improvement. See Astaqc’s guide on regression testing best practices for how to frame architectural improvements in terms of regression risk reduction.
The most expensive QA mistake at a new company is skipping the audit phase. Without a clear picture of what the test suite actually covers, you inherit invisible gaps alongside the tests themselves. The first 30 days are the highest-leverage window for establishing what quality means at this organization before sprint cadence pulls you into purely reactive work.
September 26, 2026


Sign up to receive and connect to our newsletter

We founded ASTAQC as a tight-knit group of professional Software Testers and software developers.
Subscribe to our Newsletter