September 25, 2026
Test data conflicts in parallel CI pipelines occur when two or more test workers read and write shared data concurrently without isolation boundaries between them. The canonical fix is to give each parallel worker its own data scope — through synthetic data generation, per-worker database schemas, or fixture-scoped provisioning — so that no two workers can ever operate on the same record at the same time. Secondary strategies include namespacing shared resources with worker-unique prefixes and using resource locks for genuinely shared infrastructure that cannot be isolated. The right combination depends on the data’s mutability, the test’s scope, and the infrastructure available in your CI environment. Teams that address this systematically before scaling parallel execution avoid a class of intermittent failures that are expensive to diagnose and difficult to reproduce outside CI.
This guide covers why parallel test execution creates test data problems, the primary isolation strategies with their trade-offs, how to manage shared resources that cannot be fully isolated, and a comparison of approaches by data type. For a broader treatment of how test data management fits into QA strategy, see Astaqc’s complete software testing guide and test automation services. Teams building out parallel CI pipelines can engage Astaqc’s software testing services for pipeline architecture review.
Sequential test execution has an implicit ordering guarantee: each test runs after the previous one finishes, so state changes from one test are fully committed before the next test reads or modifies related data. Parallel execution removes this guarantee. When two workers start simultaneously and both execute tests that interact with the same data layer — the same database, the same external API, the same file system path — their operations interleave unpredictably. The outcome depends on timing: which operation commits first, which lock is acquired first, whether the external service processes requests in arrival order.
The three most common conflict patterns in parallel CI are write-read conflicts (Worker A creates a record that Worker B reads expecting a different state), write-delete conflicts (Worker A creates a record that Worker B deletes as teardown), and global state conflicts (Worker A sets an environment variable or configuration flag that Worker B reads after Worker A changes it). Each pattern produces intermittent failures: they only appear when the relevant workers happen to schedule overlapping operations, which varies based on CI load, runner allocation, and execution order within each worker’s test queue.
External services compound the problem. Email delivery services, SMS gateways, and payment sandboxes often impose rate limits, share state between API calls (sandbox accounts accumulate transactions), or deliver asynchronous results (an email sent during one test arrives during a different worker’s test, captured by the wrong assertion). Teams that add parallelism to a test suite that was designed and validated in sequential execution often discover this class of failure only after the suite is running in production CI, where the combination of multiple workers and realistic timing produces conflict patterns that did not appear in local runs. See Astaqc’s AI in software testing guide for context on how AI-assisted tooling is beginning to detect these patterns automatically.
The most effective test data isolation strategy in parallel CI is to eliminate the shared state entirely by giving each worker its own isolated data scope. Three approaches achieve this at different layers of the stack, with different trade-offs in infrastructure complexity and test maintenance cost.
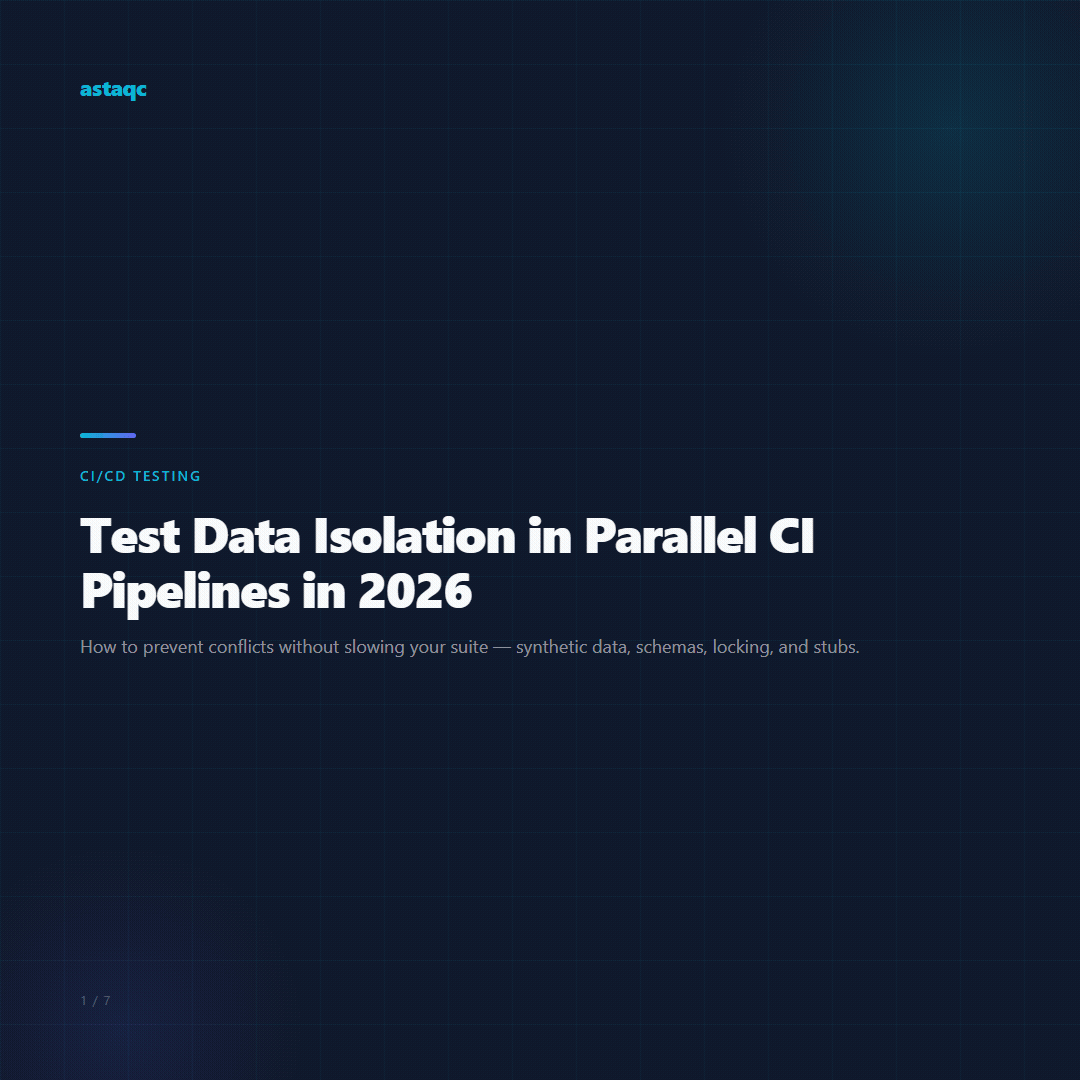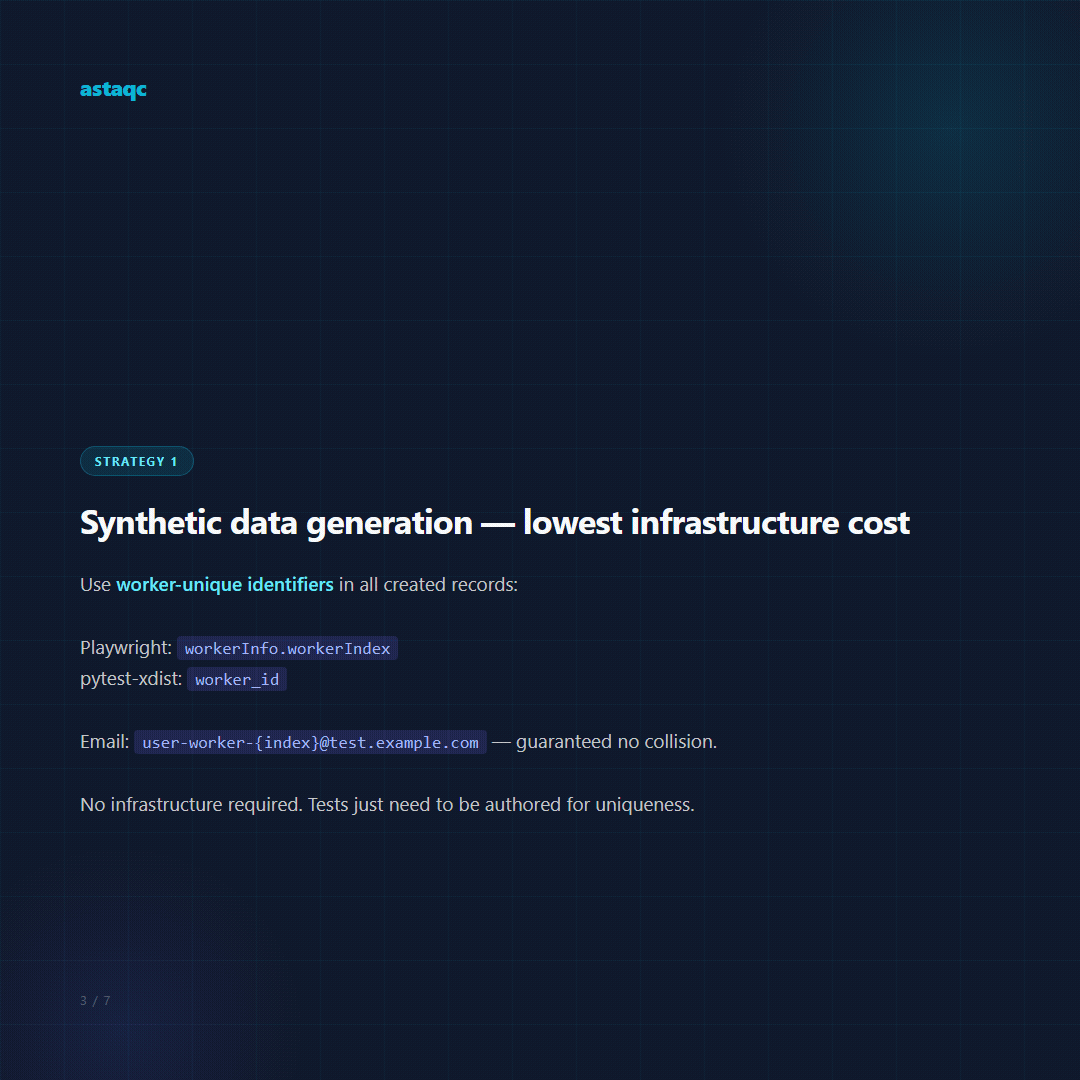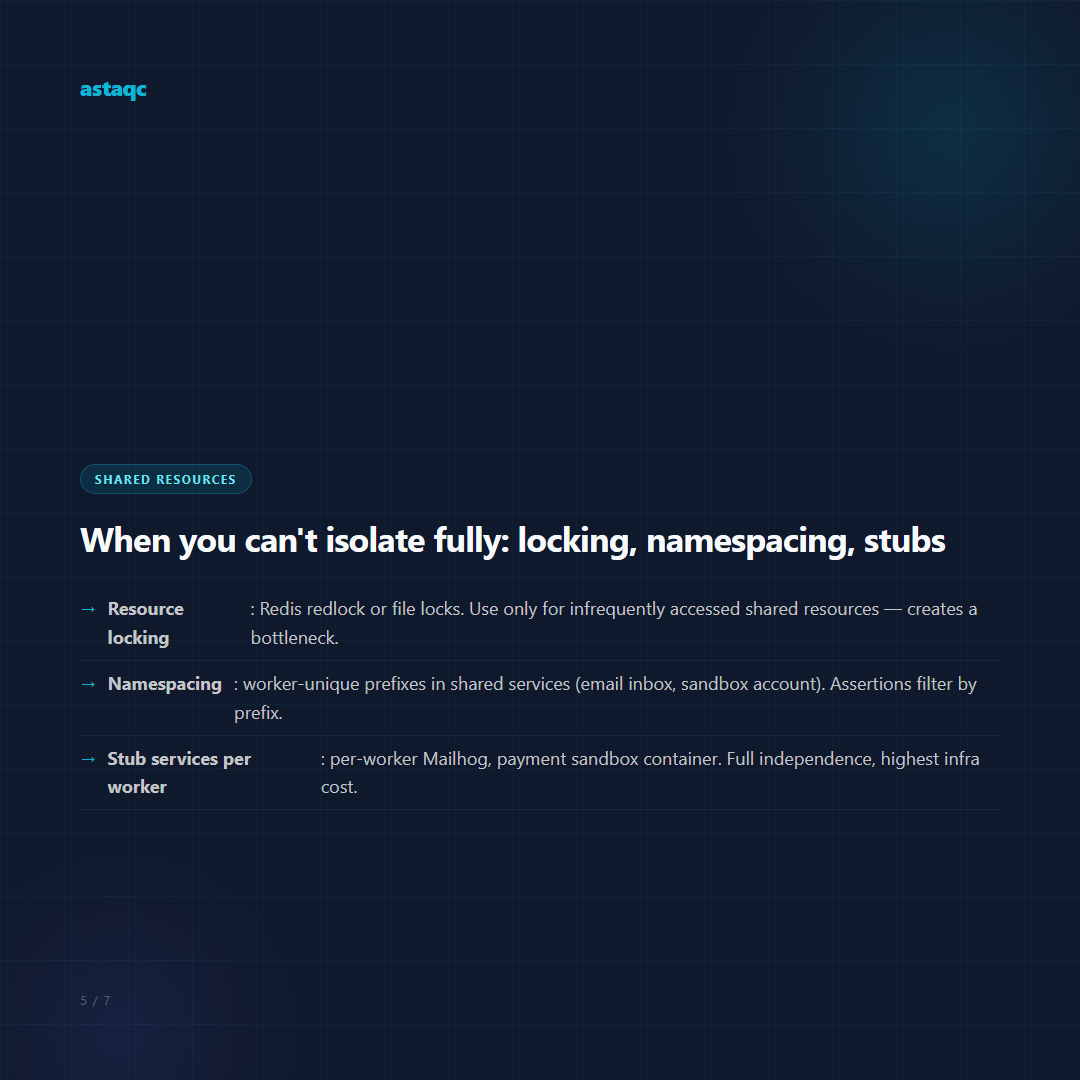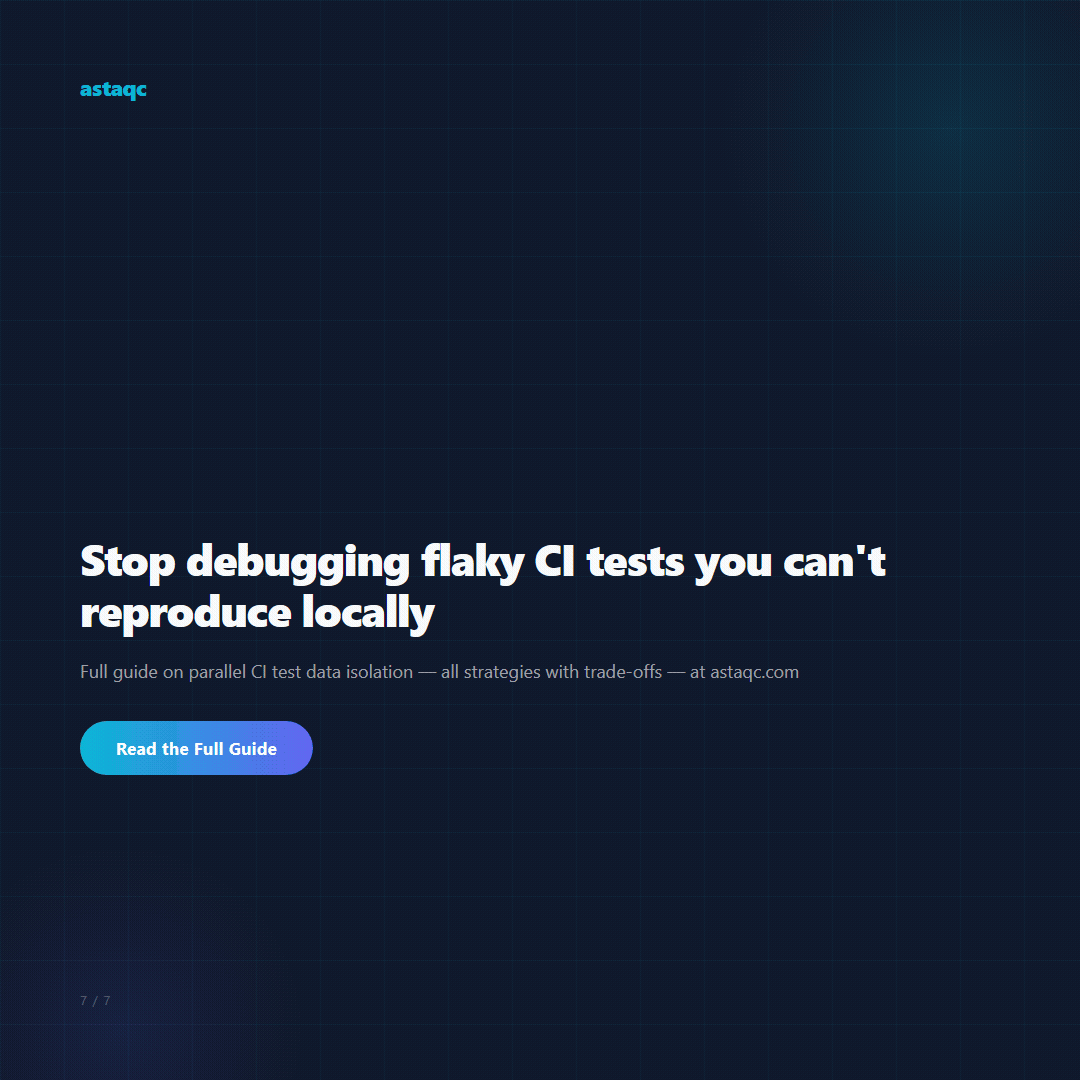
Synthetic data generation is the lowest-infrastructure approach: instead of relying on pre-existing records, tests generate unique data at runtime using worker-unique identifiers. Playwright’s workerInfo.workerIndex and pytest’s worker_id (from pytest-xdist) provide per-worker numeric identifiers that can be incorporated into generated data. A user created with email user-worker-{workerIndex}@test.example.com cannot collide with users created by other workers. For values that must be globally unique without worker coordination, timestamp-based or UUID-based suffixes achieve the same result. This approach requires no additional infrastructure but requires tests to be authored with uniqueness in mind — existing tests that reference specific pre-seeded records must be refactored to create those records dynamically.
Per-worker database schemas or namespaces provide stronger isolation by giving each CI worker a completely separate data environment within the same database instance. PostgreSQL supports schema namespacing natively: a worker can create a schema with a worker-unique name, run its tests against that schema, and drop the schema on teardown. MySQL and SQL Server support database-level isolation similarly. This approach isolates all test data in a single worker’s run without requiring tests to generate unique identifiers for every record — the schema boundary prevents any cross-worker record access. The cost is infrastructure setup: the CI pipeline must provision schemas before test execution and clean them up afterward, and the application must support schema switching via an environment variable or connection string parameter.
Fixture-scoped data provisioning is the code-based framework approach: test fixtures (beforeEach/afterEach in Playwright, conftest.py in pytest) create the data a test requires immediately before the test runs and delete it immediately after. Each test’s fixture runs within the worker’s isolated execution context, creating data that is specific to that test invocation and not accessible to other tests. This approach has the highest per-test implementation cost — every test that requires pre-existing data needs a fixture that creates it — but produces the strongest isolation guarantee: there is no shared data state between tests at all, only data created and destroyed within each test’s fixture scope. For teams using Astaqc’s test automation services to design fixture infrastructure, fixture-scoped provisioning is the recommended pattern for tests that require complex relational data setups that cannot be generated synthetically. For context on how this approach scales across team structures, see Astaqc’s manual vs. automated testing guide.
Some infrastructure cannot be fully isolated per worker: a single payment sandbox account with a limited number of test transactions, a single email delivery service that routes all messages to a shared inbox, a single external API with a rate limit that applies across all CI requests. When full isolation is not feasible, three management strategies reduce conflict probability and make conflicts diagnosable when they do occur.
Resource locking serializes access to genuinely shared resources by requiring a worker to acquire a lock before using the resource and release it after. This approach guarantees isolation but introduces a bottleneck: if the shared resource requires 5 seconds to use and you have 8 workers, the resource is a serialization point that limits parallel throughput. Locking is appropriate for resources that are shared but infrequently accessed — a specific test account used only by 2–3 tests across the entire suite, for example. It is not appropriate for resources accessed by a large fraction of tests, because the locking overhead will eliminate most of the parallelism benefit. In CI environments, locking can be implemented via Redis-based distributed locks (redlock pattern), file-based lock files on a shared file system, or CI platform-specific resource reservation mechanisms.
Namespacing does not eliminate concurrent access but makes it safe by ensuring each worker’s operations are identifiable and non-conflicting. A payment sandbox that accumulates all test transactions can be queried with a filter — worker_id prefix in the order reference, for example — so each worker’s assertions operate only on transactions it created. A shared email inbox can be filtered by recipient address, where each worker uses a worker-unique recipient (worker-1@test.example.com, worker-2@test.example.com) routed to the same inbox. Namespacing is lower cost than full isolation and lower risk than locking, making it the practical default for resources where isolation is expensive and locking would create unacceptable bottlenecks.
Stub services replace real external services with per-worker simulators that have no shared state. A mail catcher (Mailhog, Mailpit) runs as a per-worker container and captures all emails sent during that worker’s test run; each worker’s instance is independent and has no shared state with other workers’ instances. A payment sandbox emulator runs per-worker and resets between tests within each worker. This approach eliminates the external service conflict entirely but requires CI infrastructure to provision and deprovision per-worker service instances. Container orchestration (Docker Compose in CI, Kubernetes Jobs) makes this tractable for commonly needed stubs. For teams building this infrastructure, Astaqc’s software testing services include CI pipeline architecture design and performance testing services address the parallel need to verify that stub services accurately represent the performance characteristics of the real services they replace.
No single isolation strategy fits all data types or test architectures. The table below summarizes the primary approaches with their trade-offs, intended to guide selection based on specific data type and infrastructure constraints.
| Approach | Best For | Infrastructure Cost | Parallelism Impact |
|---|---|---|---|
| Synthetic data generation | Records created and consumed within a test run; no pre-existing state required | Low — no additional infrastructure | None — fully parallel |
| Per-worker database schemas | Tests requiring pre-existing relational data or complex seeding | Medium — CI pipeline must provision schemas | None — each worker has its own schema |
| Fixture-scoped provisioning | Tests with complex data dependencies that cannot be generated synthetically | Medium — fixture code per test | None — isolated per test invocation |
| Resource locking | Infrequently accessed shared resources where isolation is not feasible | Medium — lock coordination service | Serializes access to the locked resource |
| Namespacing | Shared services where isolation is impractical (email inboxes, sandbox accounts) | Low — naming convention change | None — concurrent access safe with proper filters |
| Stub services per worker | External services (email, payment, SMS) with shared state or rate limits | High — per-worker container orchestration | None — fully independent |
The practical selection process starts with inventory: for each piece of test data in your suite, classify it as worker-unique by nature (records created during the test), worker-shareable read-only (reference data that tests read but never modify), or genuinely shared mutable (records that multiple tests create, modify, and delete across the run). Worker-unique data needs synthetic generation or fixture scoping. Worker-shareable read-only data needs no isolation. Genuinely shared mutable data needs locking or stub services. Most suites have fewer genuinely shared mutable dependencies than they appear to have on first inspection; many shared resources can be converted to worker-unique by refactoring tests to create their own instances rather than relying on shared pre-seeded data. For context on structuring this audit and refactoring exercise, see Astaqc’s guide to outsourcing software testing and QA team engagement services.
Run your flaky tests with parallelism disabled (sequentially) for 20–30 runs. If the flakiness disappears or drops substantially in sequential runs, the root cause is parallel data contention rather than a timing issue in the test logic itself. This diagnostic does not require identifying which specific tests conflict — it only requires confirming that the failure rate is correlated with parallelism. Once confirmed, enable trace-level logging on the next parallel run to capture which records each worker accessed and when, which typically identifies the specific shared resource causing the conflict within one or two additional runs.
Yes. Playwright’s fixture system runs teardown code even when a test fails, because fixtures use a generator pattern where yield marks the boundary between setup and teardown. Code after the yield statement executes when the test completes, regardless of whether it passed or failed. This means fixture-scoped data provisioning can rely on teardown running without wrapping every cleanup in a try/finally block. The caveat is that teardown does not run if the CI runner crashes or is killed mid-test — for long-running tests on unreliable infrastructure, a periodic cleanup job that removes records older than a specific age is a practical safety net alongside fixture teardown.
The recommended approach is a per-worker mail catcher: a lightweight SMTP server (Mailhog, Mailpit) running as a per-worker Docker container that captures all outbound emails sent during that worker’s test run. Each worker’s mail catcher has its own isolated inbox, so emails sent during one worker’s tests cannot interfere with another worker’s assertions. The application is configured to route email to localhost:1025 (or the per-worker mail catcher port) in the CI environment, and test assertions query the mail catcher’s API for the expected message. If per-worker containers are not available, namespacing with per-worker recipient addresses routed to a single shared mail catcher is the fallback, with assertions filtering by recipient to isolate each worker’s messages.
Schema creation and seeding cost depends on the seed data volume. Creating an empty schema in PostgreSQL takes under 100 milliseconds; creating a schema and running migrations typically takes 1–5 seconds for a moderately complex application. If the seed data requires inserting many rows, the provisioning step can take 10–30 seconds per worker. For CI pipelines where test execution takes 5+ minutes per worker, this cost is acceptable. For fast suites (under 2 minutes per worker), the provisioning cost represents a meaningful fraction of total run time and may be better replaced with database snapshots (create once, restore quickly from the snapshot per worker) rather than full provisioning on each run.
Cleanup during the test run (fixture teardown, DELETE steps at end of test) is preferable to post-run bulk cleanup because it keeps data volume bounded and ensures the environment is clean for the next run even if the post-run cleanup job fails. Post-run cleanup is a safety net for data that the in-test cleanup missed — records created in tests that failed before their teardown step, for example. A practical policy is in-test cleanup for all records that tests create, with a daily post-run cleanup job that removes records matching a known test prefix and older than 24 hours as a backstop. This combination keeps the environment clean without requiring a post-run cleanup that must succeed for the next run to start cleanly.
Properly isolated tests have no ordering dependencies — each test creates its own data and cleans it up, so the order of execution across workers does not affect results. Tests that are not properly isolated have implicit ordering dependencies: Test B relies on Test A having run first to create specific data. Running these tests in parallel without addressing the ordering dependency will cause failures when the tests run on different workers or when execution order changes. The correct fix is to make Test B provision its own data rather than depending on Test A having run, not to enforce ordering. Ordering enforcement defeats the purpose of parallel execution and adds a coordination layer that increases suite maintenance cost without addressing the root cause. For teams addressing this refactoring systematically, Astaqc’s test automation services include test dependency analysis as part of CI pipeline modernization engagements.
Test data conflicts in parallel CI are intermittent, non-reproducible locally, and expensive to diagnose — because they are invisible in sequential runs and only appear when specific workers happen to schedule overlapping operations on the same record. The fix is systematic isolation, not ad-hoc workarounds: give each worker its own data scope before it needs one, and the conflicts never happen.
September 25, 2026


Sign up to receive and connect to our newsletter

We founded ASTAQC as a tight-knit group of professional Software Testers and software developers.
Subscribe to our Newsletter