October 3, 2026
How to Use TestInspector to Validate AI Chatbot and LLM Integration Flows: HTTP Steps, Response Assertions, and Non-Deterministic Output Handling Without Code
Testing AI chatbot and LLM integration flows requires validating HTTP requests to LLM provider APIs, asserting on structured response fields, and verifying that the application correctly handles the model’s output before presenting it to users. TestInspector handles this through its HTTP request steps, which send GET, POST, PUT, PATCH, or DELETE requests, capture response bodies, extract values into variables, and chain assertions across multi-step flows — without writing automation code. The approach treats the LLM integration as an HTTP boundary rather than a black box: each step asserts on observable fields (status codes, response JSON fields, error codes) rather than on the model output itself, which is non-deterministic by nature.
Teams building AI-powered applications often discover their test coverage drops sharply at the LLM integration boundary. UI tests verify what the user sees; unit tests verify component logic; but the integration layer — the prompt construction, the API call, the response parsing, the error handling — often goes untested until production failures surface it. TestInspector’s HTTP request steps close this gap by targeting the integration API directly, with variable interpolation for dynamic prompts and response path assertions for structured output validation.
Teams looking for foundational context on API testing strategy can review Astaqc’s test automation services and the manual vs automated testing guide. This article covers how to structure LLM integration tests in TestInspector, how to assert on non-deterministic outputs, and how to validate multi-turn conversation flows.
Standard API testing asserts on deterministic outputs: a given input always produces the same response. LLM integration testing cannot use this model for the model’s output itself — the same prompt sent to a large language model will produce similar but textually different responses on every call. This changes which assertions are meaningful. Asserting that the response body exactly matches an expected string will always fail for LLM output. Asserting that the response body contains a specific field, that the field is non-empty, that the HTTP status code is 200, and that a downstream system correctly processed the output is what coverage looks like for an LLM-backed endpoint.
The integration layer between an application and an LLM provider is fully deterministic and must be tested accordingly. The HTTP request structure (authentication headers, request body schema, model parameter values) is fixed. The response envelope from the provider — the fields that wrap the model output — is also fixed: providers return structured JSON where the generated content is in a known path. Asserting on the presence and structure of these envelope fields confirms that the API call is correctly formed and the response is correctly parsed, without requiring deterministic model output.
The application logic that processes the model output before presenting it to the user is also deterministic and testable. A chatbot that extracts a JSON object from a model response, validates the JSON schema, and only renders the UI after validation passes has a testable assertion surface: send a mock response with a valid JSON structure, assert that the UI renders correctly; send a mock response with an invalid JSON structure, assert that the fallback error state renders. TestInspector’s HTTP request steps, combined with variable interpolation and chained assertions, cover this surface without requiring test doubles or mocking frameworks.
TestInspector HTTP request steps accept a URL, method, request headers, and request body. For LLM integration testing, the request body contains the prompt construction — typically a JSON object with a messages array and model parameters. The step captures the full response body, and subsequent assertion steps access response fields via JSON path syntax. A step that sends a POST to an LLM API completions endpoint and asserts that the response status is 200, that the content field is non-empty, and that the token usage fields are populated covers the essential integration validation surface in three assertions.
Headers in TestInspector HTTP steps accept variable values: the Authorization header receives Bearer {{OPENAI_API_KEY}} where the variable is defined at the suite level with encrypted storage. API credentials are never hardcoded in test steps, are stored encrypted in TestInspector’s variable store, and inherit down through the test hierarchy — the key defined at the organization level is available to every test in every suite without re-entry. A team rotating API keys updates one variable, and all tests pick up the new value on the next run.
For teams testing their own application’s AI endpoint rather than the LLM provider directly, the HTTP request step targets the application’s API. The application receives the request, constructs the prompt, calls the LLM provider, processes the response, and returns a structured result. The test asserts on the application’s response, not the provider’s. This is the correct isolation point for integration testing: it validates that the application correctly processes the LLM call without the test being coupled to the specific response format of a provider that may change its API.
| LLM Integration Test Type | What to Assert | Where to Send the Request |
|---|---|---|
| Provider API health | HTTP 200, response envelope fields present | LLM provider API directly |
| Application prompt construction | Correct model, correct parameters, non-empty response | Application’s AI endpoint |
| Response parsing | Application correctly extracts structured data from LLM output | Application’s response API |
| Error handling | HTTP 429 or 5xx returns fallback, not raw error to user | Application’s AI endpoint with forced error |
| Latency | Response time within threshold for endpoint type | Application’s AI endpoint |
TestInspector’s CI/CD API trigger allows LLM integration tests to run on every deployment. The test suite can be scheduled to run continuously as a synthetic monitor for provider health — if the LLM provider’s API returns unexpected errors, the test suite fails within the scheduled run interval, and the team is alerted before user-facing failures accumulate.
The practical assertion strategies for non-deterministic LLM outputs are: existence assertions (the field is present and non-empty), schema assertions (the field is a string, number, or valid JSON object), boundary assertions (the response is under N characters or the response time is under N seconds), and negative assertions (the response does not contain specific prohibited strings). None of these require the model to produce the same output twice.
Existence assertions cover the most common failure modes in LLM integration: the model returning an empty response, the application returning null where the model output should appear, and the response envelope missing expected fields due to API version mismatches. A test step that asserts the content field is not null and is not an empty string catches all three failure modes. This single assertion, running on every CI deployment, prevents empty AI responses from reaching users.
Schema assertions are relevant when the application prompts the model to return structured output (JSON mode, function calling, or structured outputs via provider-specific APIs). A prompt that instructs the model to return a JSON object with specific fields should produce a parseable JSON object in every response when using a model that supports structured output modes. TestInspector can assert that the parsed JSON contains the expected keys with the expected types. These assertions hold regardless of the specific text the model generates.
Negative assertions are useful for content filtering and safety testing: validate that a test prompt designed to elicit a disallowed response returns either a refusal or a filtered output, not the disallowed content. TestInspector HTTP steps with variable interpolation allow the same assertion template to be reused with different prompt values by parameterizing the prompt as {{PROMPT_VAR}} and defining multiple test cases with different prompt variable values. Astaqc’s software testing services include integration test design for AI-backed applications, and the AI in software testing guide provides broader strategy context for teams building quality frameworks around AI systems.
A multi-turn chatbot conversation is a sequence of HTTP requests where each request depends on the previous response: the conversation ID or session token from turn 1 is included in the request for turn 2, and the model’s response context accumulates across turns. TestInspector models this as a sequence of HTTP request steps with variable extraction between steps. Step 1 sends the first user message and extracts session_id from the response. Step 2 includes {{session_id}} in the request body, sends the second user message, and asserts on the response. The chain continues for as many turns as the test requires.
Variable extraction from response bodies uses JSON path syntax: a response body field assigned to a named variable in the test’s variable store. The extracted value is available to all subsequent steps in the same test run. For conversation flows that involve token refresh — an LLM integration where the application periodically requests a new bearer token from the provider’s auth endpoint — the token extraction and injection follows the same pattern: an HTTP step extracts the token, and subsequent steps use the variable in the Authorization header.
Testing conversation state validity is the key assertion for multi-turn flows. After a conversation completes, assert that the application’s conversation history endpoint returns the correct turn count, that the last assistant message is non-empty, and that the conversation’s metadata fields are populated correctly. These are deterministic assertions on the conversation’s metadata, not on the model’s specific text output, and they confirm that the application’s conversation management layer is functioning correctly regardless of what the model said. Astaqc’s QA team services assist with test suite design for AI-backed applications, and the TestInspector browser extension can record a real conversation flow and convert it to HTTP test steps for use as a test template.
| Conversation Flow Step | What TestInspector Tests | Variable Involved |
|---|---|---|
| Session initialization | POST /conversations → 201, session_id present | {{SESSION_ID}} extracted |
| First user message | POST /messages → 200, assistant_message non-empty | {{MESSAGE_1_ID}} extracted |
| Second message (context retained) | POST /messages with session_id → 200, context references turn 1 | {{SESSION_ID}} injected |
| Session history retrieval | GET /conversations/{{SESSION_ID}} → 200, turn_count = 2 | {{SESSION_ID}} injected |
| Session cleanup | DELETE /conversations/{{SESSION_ID}} → 204 | {{SESSION_ID}} injected |
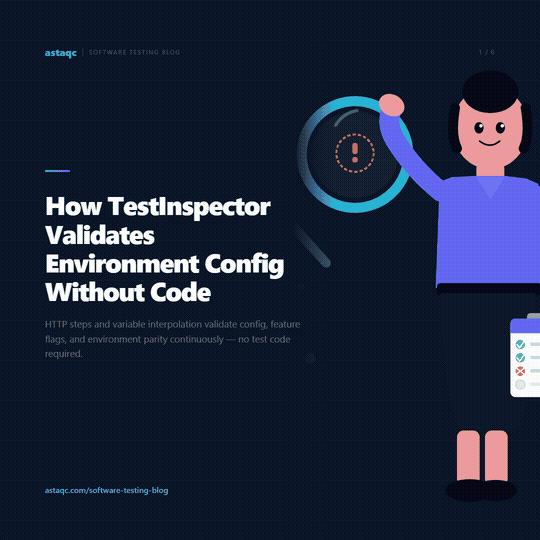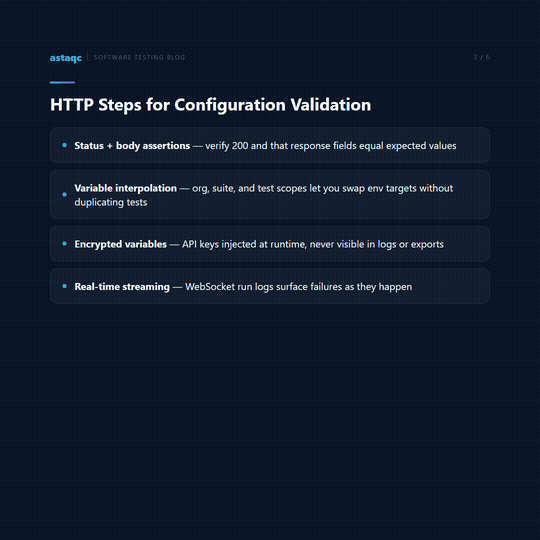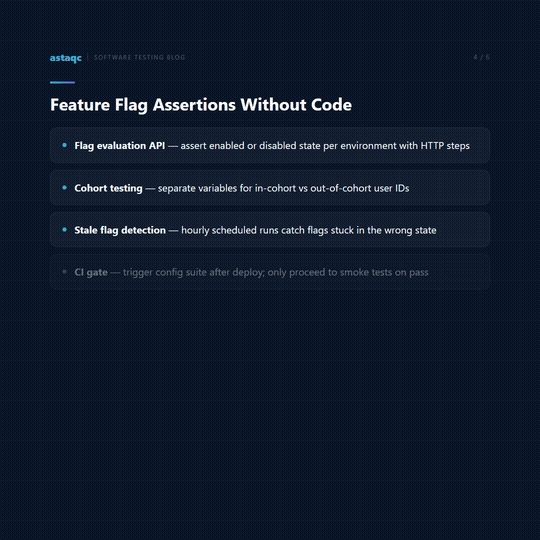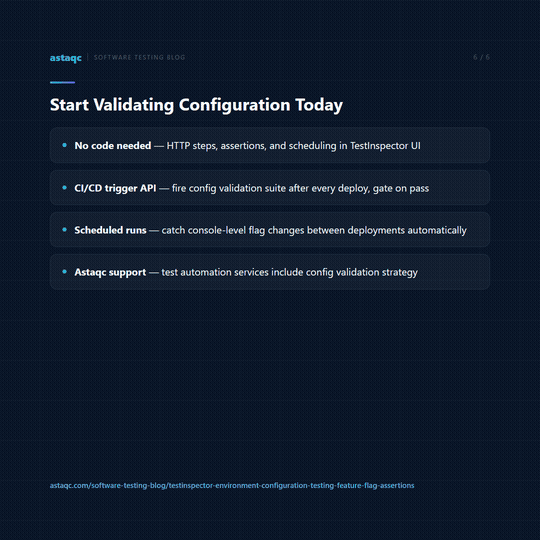
TestInspector HTTP request steps receive the complete response after the request completes. For streaming endpoints, this means TestInspector receives the full concatenated stream content after the stream closes, not individual SSE events as they arrive. This is sufficient for validating that the endpoint returns a complete, non-empty response and that the response processing layer correctly handles the streamed content. Testing the real-time behavior of individual SSE events requires a code-based testing tool with stream reading capability. For most teams, asserting on the final streamed output covers the coverage needed at the integration test level.
The practical approach is to maintain a dedicated API key for test environments with its own rate limit quota, separate from the production key. This prevents test-driven rate limit consumption from affecting production users. Store the test-environment key as a TestInspector variable at the organization level with encrypted storage, and configure the CI pipeline to use that key via environment-specific variable overrides. Run LLM integration tests less frequently than unit and functional tests — on deploy to staging and on scheduled runs, not on every commit — to stay within tier limits. Astaqc’s test automation services include CI/CD test scheduling strategy for AI-backed applications.
TestInspector assertion steps include contains checks for text fields. For LLM response content, a contains assertion confirms that the response includes a specific phrase or keyword that should always appear given the prompt. A customer support chatbot prompted to always include a case reference number format should always return a string matching the expected format. Contains assertions work alongside non-empty existence assertions to give partial coverage of non-deterministic content without coupling to specific model phrasing.
Error handling tests require a test environment where the LLM provider endpoint can be substituted with a mock that returns error responses on demand. In an application with a configurable provider base URL, point the test environment at a mock server that returns 429, 500, or a timeout, and assert that the application returns the correct fallback response to users rather than a raw error. If the application has no configurable endpoint, error handling tests require integration with the application’s error injection mechanism. Astaqc’s software testing services include test architecture review for teams building error injection capability into AI-backed systems.
LLM integration tests sit at the service integration layer — above unit tests and below end-to-end UI tests. They run on deployment to staging environments and on scheduled synthetic monitoring runs in production. The test count is small: typically 5–15 tests covering provider health, prompt construction, response parsing, error handling, and multi-turn flows. Coverage quality matters more than count — a well-designed 10-test LLM integration suite catches more production issues than a 100-test suite with redundant assertions. TestInspector’s scheduling capability makes it straightforward to run these tests on a cron schedule as a production health monitor alongside standard API health checks. For broader cost planning on AI testing programs, the software testing cost guide covers how to estimate scope and investment for AI integration test suites.
LLM integration testing requires rethinking what a useful assertion looks like. The model’s output is non-deterministic — asserting on its specific text will always fail. Asserting on the envelope, the structure, the status code, and the downstream processing confirms that the integration is working correctly without coupling tests to model phrasing.
October 3, 2026


Sign up to receive and connect to our newsletter

We founded ASTAQC as a tight-knit group of professional Software Testers and software developers.
Subscribe to our Newsletter