October 23, 2026
Form validation testing in web applications requires a structured approach to input boundary conditions, error message correctness, and state transition behavior that goes beyond submitting invalid data and checking whether an error appears. Effective form validation test coverage includes required field enforcement at whitespace boundaries, character limit testing at exact limits, format validation at the boundary between pattern-matching and bypass inputs, and validation state reset testing across navigation events. Building this coverage with automated tools requires assertions that verify specific DOM states, not just page-level outcomes.
The practical challenge is that form validation logic has three outputs — the error message text, the field state change, and the form submission behavior — and production bugs commonly involve one of these being correct while the others are broken. A form that displays the right error message but does not apply aria-invalid to the field is accessible-testing-broken. A form that applies the correct ARIA attributes but allows submission anyway is functionally broken. Test coverage that checks only one of these outputs misses the others. This guide covers how to build test cases that verify all three outputs for the validation scenarios most likely to contain production bugs in 2026 web applications. Astaqc's software testing services page covers how form validation fits into full-stack functional test planning.
Boundary value analysis for form validation identifies the input values where validation logic is most likely to fail. These are not arbitrary edge cases — they are the values at the boundaries of each validation rule, where a small change to the rule or the input would flip the validation outcome. Testing boundary values rather than arbitrary invalid inputs produces tests that are sensitive to regressions in validation logic without requiring large numbers of test cases.
For required fields, the boundary values are: empty string (clearly invalid), whitespace-only string (invalid in most specifications but often passes naive implementations), a single non-whitespace character (the minimal valid input), and a string that meets other requirements but fails a different validation rule. The whitespace case is particularly important because many frontend frameworks use value.length rather than value.trim().length for required checks, and a field pre-filled with a space character by autocomplete passes a naive check.
For character limits, the standard boundary values are: one below the limit (valid), exactly at the limit (valid, at the boundary), one above the limit (invalid, at the boundary), and significantly above the limit. Testing at and around the limit catches both off-by-one errors in the validation logic and UI behaviors like character counters that display incorrectly at the exact limit. Astaqc's test automation services page covers how boundary value analysis is applied in automated test planning for web application test suites.
Error message assertions should match the exact text the specification defines rather than a partial string that would pass for multiple different messages. A test that checks for "valid email" would pass if the error message reads "Enter a valid email address," "This email is not valid," or "Invalid email" — three different messages with different user impact and different implied corrections. Asserting the exact string catches regressions where error messages are changed to something less informative, combined into a generic message, or accidentally removed.
The practical argument for exact-match error assertions is that error messages are user-facing specification outputs. If the specification says a required field should display "This field is required" and the implementation displays "Required," that is a discrepancy. A partial-match assertion would not catch it. A user reading "Required" when the specification says "This field is required" is experiencing exactly the kind of UX inconsistency that appears in design reviews and usability studies — but only if someone is checking.
Error message assertions should also verify the absence of error messages after valid input is provided. A form that shows a stale error message from a previous invalid submission after the user has corrected the input and re-submitted is broken — the error should be cleared, not persist. Testing this requires an assert-not-visible or assert-empty step after providing valid input in a field that previously showed an error.
| Assertion Type | What It Catches | When to Use It |
|---|---|---|
| Exact text match | Changed, truncated, or genericized error messages | Every validation rule with a specified error message |
| Visible assertion | Error that is in DOM but hidden, or missing entirely | Validation triggered by form submit or blur events |
| Attribute assertion | Missing ARIA attributes, wrong disabled state | Accessibility-required state changes on the input element |
| Not-visible assertion | Stale error persisting after correction | After providing valid input following an error state |
Form validation in modern web applications fires at three different trigger points: on each input event (real-time validation as the user types), on blur (when the user leaves the field), and on form submit (when the user attempts to submit). Different validation rules should fire at different points for a good user experience — character limit feedback works well as real-time validation, required field errors work better on blur, and complex server-side validation necessarily fires on submit. The test strategy for each trigger point differs because the interaction sequence that produces the validation state differs.
Real-time validation tests must simulate the timing of user input. A test that sets a field's value directly to a 51-character string using an automation API may not trigger character-count validation that listens on input events, because setting the value programmatically does not dispatch input events in all automation frameworks. Tests that need to trigger real-time validation should type the input character by character, or at minimum dispatch the input event explicitly after setting the value. For debounced real-time validation, a pause step between input and assertion ensures the debounce period has elapsed before checking the validation state.
Blur-triggered validation tests require an explicit blur action after filling the field — typically clicking elsewhere on the page or pressing Tab — before asserting the error state. A common test construction error is to fill the field, then immediately assert the validation state without triggering the blur event. This test passes locally (where the automation framework happens to blur the field as a side effect of clicking the assert target) and fails in CI (where no click follows the fill). Writing the blur action explicitly prevents this environment-dependent flakiness.
Submit-triggered validation tests must attempt form submission and assert that the form does not advance to a success state while asserting that the error messages appear. The assertion sequence matters: check that you are still on the form (the URL has not changed, the success message is not visible), then check that the specific error messages appear. This order catches a regression where the form submits successfully but the validation errors also appear, which would pass a test that only checks for error presence. Astaqc's manual testing services page covers exploratory testing of form validation timing behaviors that are difficult to catch with purely automated test suites.
The form validation edge cases most commonly found in production bugs are not the ones covered by a simple invalid-input test. They appear in specific interaction paths — input methods that behave differently from keyboard typing, navigation events that should reset state but don't, and keyboard navigation paths that bypass mouse-triggered validation.
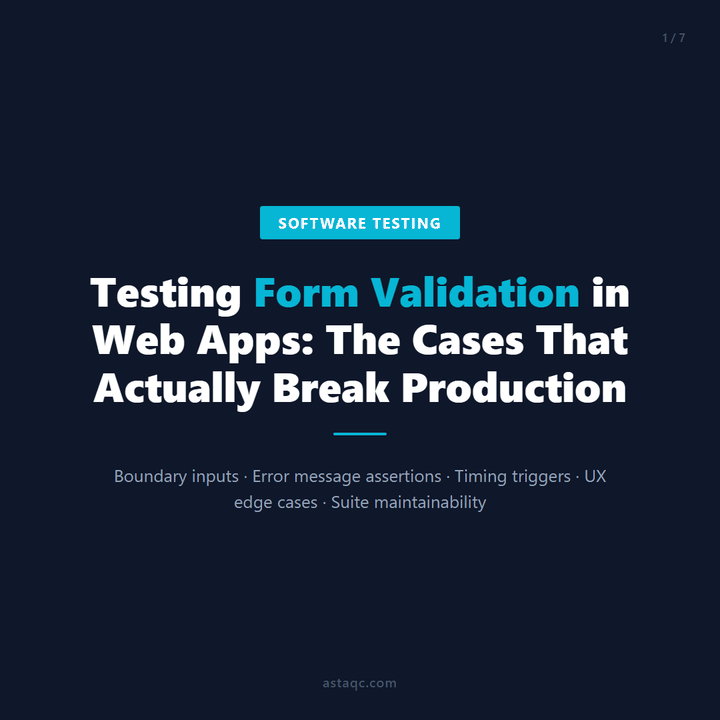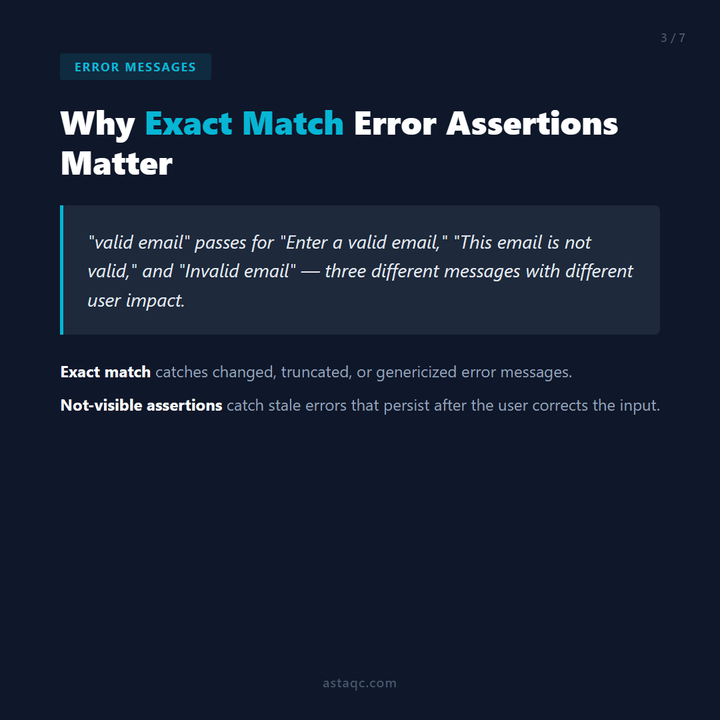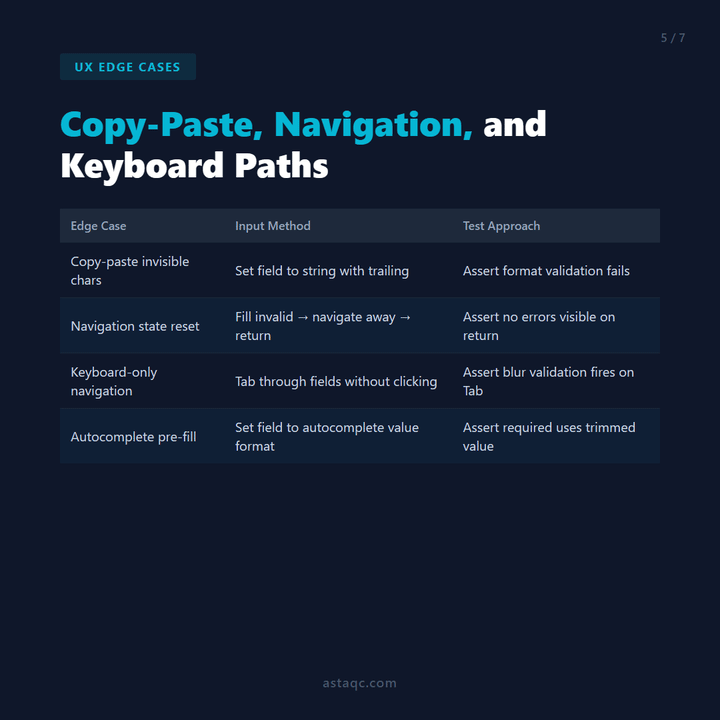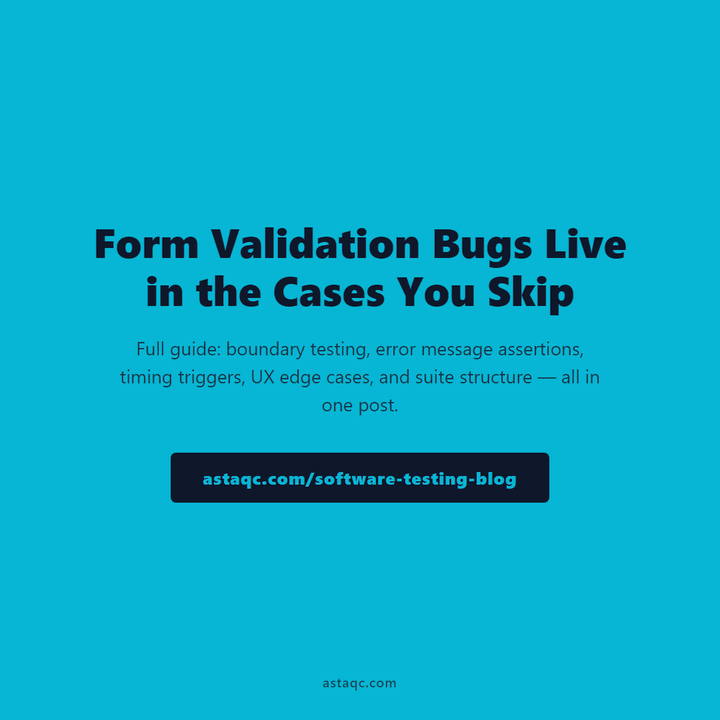
Copy-paste inputs introduce whitespace and invisible characters that keyboard typing does not. A user pasting an email address from a document may include a trailing non-breaking space character (Unicode ), which format validation patterns often do not match against, producing a false-valid result that the backend then rejects. Testing copy-paste scenarios requires setting the field value to a string that includes these characters rather than relying on typed input. For applications where copy-paste from specific sources is a documented user workflow, these tests are first-class regression cases, not edge cases.
Navigation reset testing verifies that validation state is cleared when the user navigates away from a form and returns. Single-page applications using client-side routing are especially prone to this issue: a React component that stores validation state in local state rather than resetting it on unmount will show the previous session's errors when the user navigates away and back. A test that fills a form with invalid data, navigates to another route, returns to the form, and asserts that no error messages are visible validates this reset behavior.
| Edge Case Category | Input Method | Test Approach |
|---|---|---|
| Copy-paste invisible chars | Set field value with trailing or | Assert format validation fails and error appears |
| Navigation state reset | Fill invalid → navigate away → navigate back | Assert no errors visible on return |
| Keyboard-only navigation | Tab through fields without clicking | Assert blur validation fires on Tab-triggered blur |
| Autocomplete pre-fill | Set field to browser-autocomplete value format | Assert required check uses trimmed value |
Astaqc's dedicated QA team page covers how UX edge case testing is structured in QA engagements alongside functional automation.
Form validation test suites grow large quickly when every validation rule has multiple test cases. A suite that started with ten rules and three test cases per rule becomes a thirty-test suite that takes effort to maintain when the form changes. The structural patterns that keep form validation suites maintainable are: one suite per form section rather than per validation rule, variables for input values rather than hardcoded strings, and separate suites for boundary cases versus typical-use flows.
One test per validation rule — not one test for all invalid inputs together — is the most important structural decision. A test that fills a form with multiple invalid inputs and asserts a single error message cannot distinguish a regression in rule A from a regression in rule B. When that test fails, the diagnosis step is to manually inspect the form to find which rule broke. One test per rule means every failure names the broken rule directly in the test result. The increased number of tests is offset by the reduced time to diagnose failures.
Variable-driven input values keep the suite readable and adaptable. A test that uses {{VALID_EMAIL}}, {{INVALID_EMAIL_NO_AT}}, and {{INVALID_EMAIL_TRAILING_SPACE}} as input variables is readable at the step level and adaptable at the suite level: changing the valid email format for a new environment means changing one variable, not editing every step that uses an email. This pattern also makes it easy to run the same suite with multiple input sets by changing the variable values without modifying test steps.
Grouping boundary-case suites separately from flow suites allows running the full boundary suite as a regression check and running only the happy-path flows in time-sensitive CI contexts. Boundary cases are valuable as regression tests but are not needed on every deployment — running them nightly or on staging before production release gives coverage without slowing the main CI pipeline.
A required text field with no other validation rules needs four test cases: submit empty and assert the error message appears; submit with whitespace-only content and assert the error message appears; submit with one valid character and assert no error; submit with a valid full input and assert the form accepts it. If the field has a character limit, add the four boundary cases around the limit. If the field has format requirements, add a valid format case, an invalid format case, and at least one boundary-valid case. This set covers the most common production bugs in required field validation without being exhaustive.
Fields with server-side validation — email uniqueness, username availability, address verification — require both a UI assertion and an API assertion. The UI test fills the field with an input that triggers server-side rejection, submits the form, and asserts that the server-returned error message appears in the UI. The API test verifies that the rejection returns the correct status code and error payload. These tests use different input values than client-side validation tests: the input that reaches the server should be a value that passes client-side validation but fails server-side (for example, an email that is correctly formatted but already registered), not a value that never gets past the client.
Functional testing verifies that validation logic produces the correct outcome — the right error message, the form does not submit with invalid data. Accessibility testing verifies that the DOM state changes required for assistive technology are made correctly: aria-invalid="true" is set on the input after failed validation, aria-describedby points to the error message element, the error message element has a role that assistive technology will announce, and the error is announced when it appears rather than only when the user navigates to the field. These are separate checks; a form can be functionally correct (the right error text is visible) while being accessibility-broken (the error is not announced by a screen reader).
Happy-path form validation tests should run on every PR that touches form logic — they are fast and catch the most common regressions. Boundary-case tests should run on every staging deployment before a production release. Full edge-case suites including copy-paste, navigation, and keyboard-path tests should run at minimum weekly and before any major release. This schedule gives progressive coverage depth as the stakes of the deployment increase, without blocking fast CI cycles with slow test runs.
Unit tests cover validation logic that is implemented as pure functions — a function that checks whether a string is a valid email can be tested directly with a range of inputs. End-to-end automation covers validation behavior at the UI level: the event triggers, the DOM state changes, the error message visibility, and the form submit behavior. Both are needed. A unit test that the validation function correctly identifies invalid emails does not verify that the function is actually called on blur, that its result is applied to the correct DOM element, or that the element update is performed in the right order. UI-level automation is the only way to verify the integration of the validation logic with the UI behavior.
The form validation bugs that reach production are not the obvious ones. They appear at the intersection of two rules, in timing-dependent paths where validation fires before input completes, and in error recovery flows where the validation state is correct but the UI behavior after correction is broken. Covering these cases requires testing beyond the happy path with explicit boundary inputs and state transition assertions.
October 23, 2026


Sign up to receive and connect to our newsletter

We founded ASTAQC as a tight-knit group of professional Software Testers and software developers.
Subscribe to our Newsletter


