October 12, 2026
Property-based testing is a technique where the test framework generates hundreds or thousands of randomized inputs and checks that a defined property holds across all of them, rather than requiring the engineer to specify individual input-output pairs. A hand-written test asserts that sorting [3, 1, 2] returns [1, 2, 3]; a property-based test asserts that for any list of integers, the sorted result is ordered — every element is less than or equal to the next — and the framework generates thousands of random lists to check this. When the assertion fails on an unexpected input, the framework shrinks the failing case to the smallest example that still triggers the failure, making the bug easy to diagnose. The technique originated in Haskell's QuickCheck in 1999 and has since been implemented in Python (Hypothesis), JavaScript (fast-check), Java (jqwik), Elixir (PropCheck), Go (gopter), Rust (proptest), and most other modern languages. In 2026, it is used in CI pipelines for business logic, data serialization, API contract validation, and security-sensitive parsing — any area where hand-written examples cover a small fraction of the valid input space.
A property-based test has three components: a generator, a property, and a shrinking strategy. The generator produces random values of the required type — integers, strings, lists, date ranges, structured objects, or any combination. The property is the invariant the function must satisfy across all generated inputs: a sort function's output must be in ascending order, a JSON serializer's output must be valid JSON, an idempotent function's result must be unchanged when applied twice. The framework runs the test hundreds of times with different generated inputs, checking the property on each one.
When a property fails, the framework does not simply report the failing input — it shrinks it. Shrinking is the process of finding the smallest, simplest input that still causes the failure. If a parser fails on a 500-character string, the shrinker finds whether it also fails on a 100-character string, then a 50-character string, and so on, until it isolates the minimal reproducing case. The resulting failure report is significantly easier to debug than the original random input. Shrinking is why property-based testing produces actionable bug reports rather than just large random failures.
Stateful property-based testing extends this approach to sequences of operations: the framework generates random sequences of API calls, database operations, or in-memory function calls and checks that a set of model invariants holds after each step. This is used to test state machines, in-memory data structures, and APIs that maintain server-side state. Astaqc's test automation services include property-based testing strategy for teams introducing it into existing pipelines. The complete software testing guide covers where property-based testing fits in the broader quality strategy.
The bugs property-based testing finds are edge cases at the boundaries of the input space — inputs that engineers do not think to write as examples because they are uncommon, counterintuitive, or too tedious to enumerate. Four categories appear repeatedly in production codebases.
Boundary and overflow bugs occur at the edges of numeric ranges: maximum integer values, zero, negative zero, NaN, infinity, empty collections, single-element collections. Example-based tests typically cover a handful of representative values; property-based tests cover the full boundary set by generating values near the edges of each numeric type's range. Functions that handle currency arithmetic, date arithmetic, or pagination are common sources of boundary bugs that property-based tests reliably surface.
Unicode and encoding bugs appear in string-handling functions. Hand-written string tests use ASCII inputs because they are easy to type. Property-based tests generate strings with Unicode characters, zero-width characters, right-to-left characters, multi-byte sequences, and null bytes. Functions that parse user-provided strings, sanitize HTML, truncate text to a display length, or hash input strings frequently fail on Unicode edge cases that example tests do not surface.
Commutativity and symmetry violations appear in functions that should behave consistently across equivalent inputs. A serializer and deserializer that are not perfect inverses — where deserializing a serialized value does not return the original — is caught by the roundtrip property: for any value, deserialize(serialize(x)) == x. A comparison function that violates transitivity is caught by the ordering property. These bugs are almost never caught by hand-written example tests because they require discovering the specific input pair that triggers the inconsistency.
Concurrency and ordering bugs are surfaced by stateful property-based tests that generate random operation sequences. A function that behaves correctly in a specific order but fails when the order changes requires property-based testing to find reliably. Astaqc's software testing services include expert-led property-based testing for high-risk components. The manual vs. automated testing guide covers how exploratory testing complements property-based approaches.
The library landscape in 2026 is mature across all major languages. Each implements the same conceptual model — generators, properties, shrinking — with language-idiomatic APIs and varying levels of built-in generator coverage.
| Library | Language | Key strength | Shrinking |
|---|---|---|---|
| Hypothesis | Python | Largest built-in strategy library; failure database across runs | Integrated (best-in-class) |
| fast-check | JavaScript/TypeScript | Strong TypeScript types; async property support; model-based testing | Integrated |
| jqwik | Java | JUnit 5 integration; annotation-driven generators | Integrated |
| proptest | Rust | Macro-based strategy derivation; persistent failure database | Integrated |
| gopter | Go | Stateful testing via commands; integrates with testing.T | Integrated |
| FsCheck | F# / C# | NUnit and xUnit integration; .NET type inference for generators | Integrated |
| PropCheck | Elixir | StreamData-based; integrates with ExUnit | Integrated |
Hypothesis is the most developed library in terms of generator coverage and shrinking quality. Its database feature persists failing cases across runs so that a bug found in one CI run is retested in every subsequent run until the code changes. fast-check's TypeScript support and async property API make it the standard choice for Node.js and TypeScript projects. jqwik's JUnit 5 integration makes it the least-friction option for Java projects already using JUnit 5. Astaqc's performance testing page covers how property-based testing applies to performance invariants in addition to correctness properties.
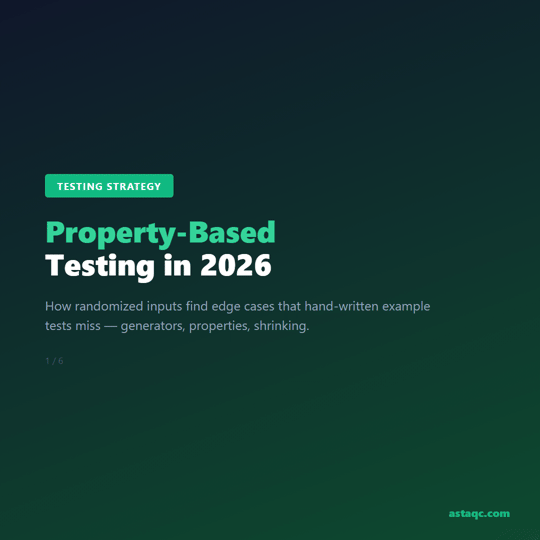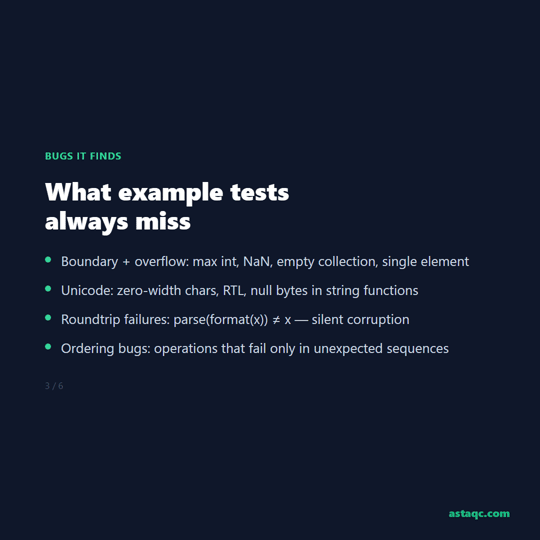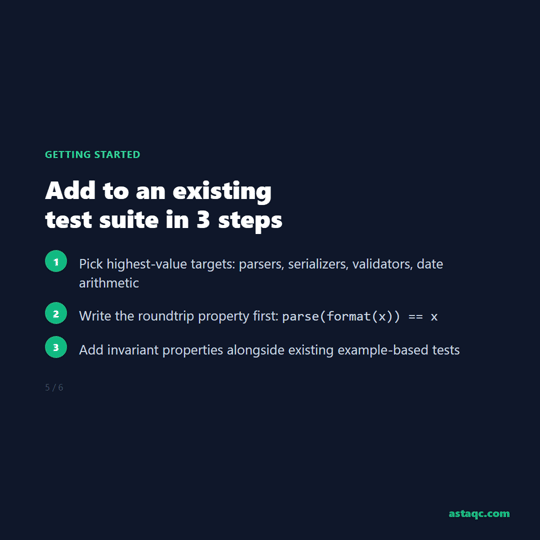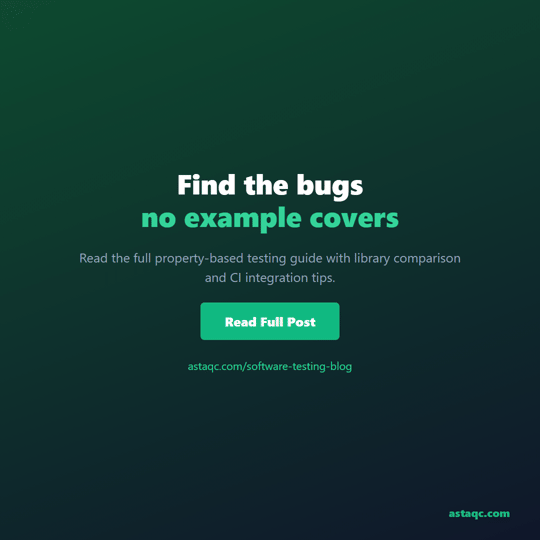
Property-based testing does not replace example-based tests — it adds coverage for the input space that example tests cannot efficiently enumerate. The practical approach is to identify the highest-value targets in the existing codebase, write the first properties alongside existing example tests, and expand incrementally.
The highest-value targets are functions with large valid input spaces and business-critical correctness requirements: parsers, serializers, validators, business rule engines, sorting and ranking functions, date and time arithmetic, and functions that handle user-provided strings. Security-sensitive functions — input sanitizers, authorization rule evaluators, cryptographic utilities — are especially high-value because incorrect edge case handling has direct security consequences.
The first property to write for any function is usually the roundtrip property: if the function has an inverse, verify that the composed function returns the original input. parse(format(x)) == x for a date formatter, decode(encode(x)) == x for a serializer. Roundtrip properties require minimal domain knowledge to express and find a class of bugs that example tests rarely catch. The second category is invariant properties: assertions that must hold for any valid output — a sort function's output must be ordered and contain the same elements as the input, a filter function's output must be a subset of the input.
Integration into CI/CD is straightforward: property-based tests run alongside unit tests in the same test command and produce standard pass/fail output with minimal-reproducing-case failure reports. The main operational consideration is run count: more iterations find more edge cases but increase test time. Production defaults are typically 100 to 500 iterations per property. Teams using Hypothesis can set a deadline to prevent slow tests from blocking CI. Astaqc's testing documentation services include property inventory documentation for teams formalizing which properties are tested. The AI in software testing guide covers how property-based testing integrates with AI-assisted test generation in 2026.
Fuzz testing and property-based testing both generate random inputs, but they serve different purposes. Fuzz testing targets parsing layers and security boundaries — it generates malformed and mutation-of-known-good inputs to find crashes, panics, and memory safety violations. Property-based testing targets business logic and correctness properties — it generates valid inputs of the required type and checks that defined invariants hold. A fuzzer for a JSON parser looks for inputs that cause crashes; a property test checks that the parser correctly handles all valid JSON structures. The two techniques are complementary, not interchangeable.
Property-based tests run more iterations than example-based tests, so they are slower by iteration count. In practice, each iteration is fast (milliseconds for pure functions), and suites typically run 100 to 500 iterations per property by default. A test suite with 50 property-based tests at 200 iterations each adds roughly 10 seconds if each iteration runs in 1ms. Libraries like Hypothesis support a deadline parameter that limits wall-clock time per property, preventing slow tests from blocking CI. The time cost is proportionate to the added coverage.
Property-based testing is most productive for pure or near-pure functions with well-defined input and output types. UI and integration tests involve multiple systems, external state, and side effects that make it difficult to define clean properties and run many iterations without cost. Stateful property-based testing is applicable to API-level testing when the test environment is fast and isolated. For UI tests, the overhead of browser automation per iteration makes hundreds of iterations impractical. Property-based testing's primary value is in the business logic and data transformation layers, not in end-to-end flows.
Most property-based testing libraries provide composable generator primitives: integers in a range, strings from a character set, elements from a list, nullable versions of any type. Custom generators for domain objects are built by composing these primitives — a valid UserAccount generator combines an integer generator for the ID, a string generator constrained to valid email patterns for the email field, and a list generator for roles. Libraries like Hypothesis (Python) and jqwik (Java) also support deriving generators from type annotations, which reduces boilerplate for standard domain object shapes.
Property-based testing and example-based testing are complementary. Example-based tests are precise: they verify known scenarios with exact expected outputs and document intended behavior through specific cases. Property-based tests are broad: they cover the full input space for a property and find edge cases that examples miss. The practical approach is to keep example-based tests for known scenarios and expected behaviors, and add property-based tests for the input-space coverage that examples cannot enumerate. Astaqc's test automation services cover combining both approaches in a unified test strategy.
Most property-based testing libraries record the failing seed when a property fails, so the failure can be reproduced deterministically by re-running with that seed. Hypothesis stores failing cases in a persistent database and replays them on every subsequent run, independently of random seed. Flaky property-based tests that fail on one CI run and pass on the next are usually caused by a real but rare edge case rather than test infrastructure flakiness — the failure rate is determined by how often the generator hits the triggering input. When a property fails intermittently, the correct response is to investigate the failing case, not to dismiss it as noise.
October 12, 2026


Sign up to receive and connect to our newsletter

We founded ASTAQC as a tight-knit group of professional Software Testers and software developers.
Subscribe to our Newsletter